
SFTP Integration
In this article
In this article group
- Amazon Connect
- Apple App Store
- Census Integration
- Connect Plain to Enterpret
- Decagon Integration
- Discord
- Discourse Integration
- Email Integration
- Facebook Pages Integration
- Fathom Integration
- File Upload: CSV data on Enterpret
- Freshchat
- Freshdesk
- Front
- G2
- Gainsight Communities Integration
- GitHub Issues Integration
- Gong Integration
- Google My Business Integration
- Google Play Store
- Grain
- Granola Integration
- Import HubSpot feedback
- Instagram Comments Integration
- Intercom
- Kustomer
- Livechat Integration
- SurveyMonkey
- Pylon integration
- Qualtrics
- Refiner Integration
- Salesforce
- Slack feedback ingestion: setup and troubleshooting
- Snowflake
- Sprig Integration
- Stella Connect
- TikTok Integration
- Trustpilot Integration
- Typeform
- X (formerly Twitter) Integration
- Connect YouTube videos and comments
- Zendesk Chat
- Zendesk Support
- Import Zoho Desk support tickets
- Zoom Integration
- Zapier Integration
- Reddit Search (UGC)
- Wispr Flow integration
The SFTP integration lets you deliver feedback to Enterpret by dropping JSON, JSONL/NDJSON, CSV, TSV, or ZIP files onto an SFTP server we connect to. Enterpret polls that server on a fixed schedule, picks up new files, parses them, and processes eligible records. It's the right choice when you can't push to a webhook (batch exports, nightly jobs, vendor-provided feeds) but can produce supported export files on a schedule.
SFTP record schema: SFTP uses the flat REVIEW record schema documented below. Use Webhook Integration for structured Conversation, Survey, or Audio payloads. The Webhook metadata schema differs from SFTP.
How it works
You give Enterpret a set of SFTP credentials and a remote directory.
Enterpret polls that directory on a schedule.
On each poll we list the directory, pick the next file in
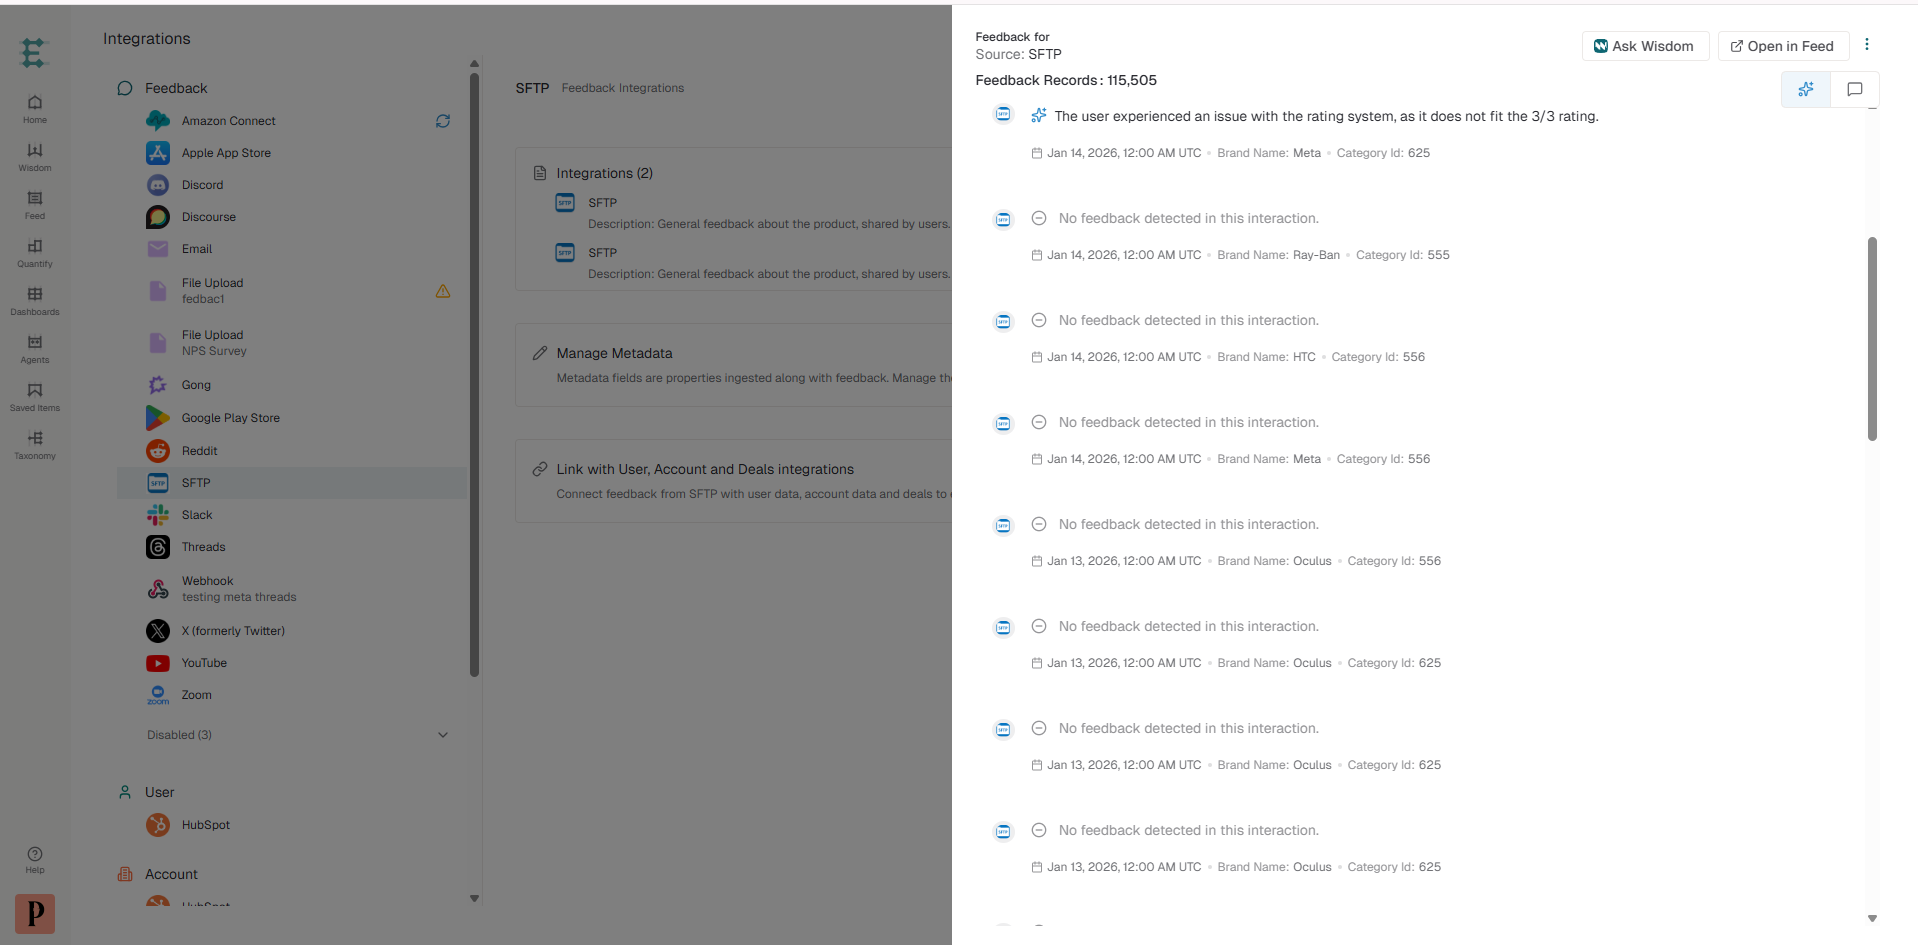
(modified-time, name)order, and stream-parse it.Eligible records are validated and ingested. When failed-record storage is configured, invalid records are uploaded to an Enterpret-managed S3 location for investigation. Upload failures can also occur. The image below illustrates records after successful processing.
Once a file is fully drained, Enterpret advances its internal "watermark" so the same file is never reprocessed (unless you re-upload it with a new modified time).
We never delete or modify files on your server. Cleanup is your responsibility.
What we need from you to get set up
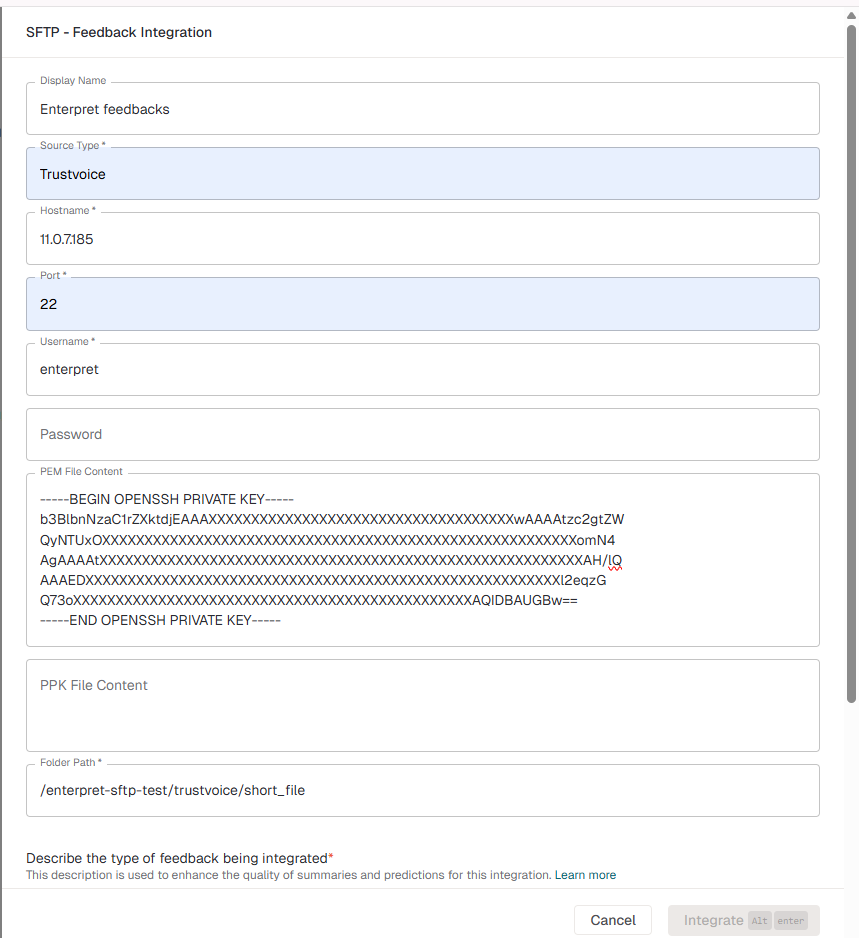
Send the following to your CSM or Enterpret point of contact. Complete the required fields shown in the setup form, including Source Type, Hostname, Port, Username, Folder Path, and authentication details. Contact your Enterpret team for assisted setup.
Field | Description | Example |
Source type | A short label that identifies this feed downstream (used for filtering in the dashboard). Free-form. |
|
Hostname | SFTP server hostname or IP. |
|
Port | Required SFTP port. Use |
|
Username | The user Enterpret will log in as. We strongly recommend a dedicated read-only user. |
|
Authentication | One of: password, PEM private key, or PPK private key. Use password authentication or a private key; an encrypted key can also require a passphrase. | (see below) |
Remote directory | Absolute path on the SFTP server where you'll drop files. |
|
SSH host key fingerprint | Captured automatically on the first successful setup connection (trust on first use). Later connections verify the stored key. |
|
Authentication options
Choose an authentication method:
Password — simplest, but rotate regularly.
PEM private key — OpenSSH format. The corresponding public key must be in the user's
~/.ssh/authorized_keyson your server.PPK private key — PuTTY format. Same authorized-keys requirement.
🔐 Encrypted private keys are supported. If your PEM or PPK is passphrase-protected, send the passphrase in the **password** field. The integration uses the same field for both SSH-password auth and key passphrase — never both at once.
Credentials are stored encrypted at rest. If you ever need to rotate, contact us — we'll update the integration in place.
Why we need the host key fingerprint
During initial setup, Enterpret captures the server’s SSH host-key fingerprint from the first successful connection (trust on first use). Later polls verify that stored fingerprint and fail if the server presents a different key. First-use capture does not independently verify the server’s identity; confirm the intended server before connecting.
You can grab the fingerprint with:
ssh-keyscan -t rsa,ed25519 sftp.acme.com 2>/dev/null | ssh-keygen -lf -
Use a trusted server-administration channel to check the SHA256:… value if your security team needs to validate the captured key.
File requirements
Supported formats
Supported file extensions are .json, .jsonl, .ndjson, .csv, .tsv, and .zip. Extension matching is case-insensitive.
| Format | Required layout |
|---|---|
| JSONL / NDJSON | One complete JSON object per line. Use real line breaks between records, with no commas or wrapping array. |
| JSON | A JSON array of record objects, or newline-delimited JSON objects. |
| CSV / TSV | UTF-8 text with a header row. Use comma-separated CSV or tab-separated TSV. Required headers are id, type, text, and either timestamp or createdAt. Header names are case-sensitive. Other nonempty columns become string metadata. |
| ZIP | An unencrypted ZIP containing any mix of the supported JSON, JSONL/NDJSON, CSV, and TSV data files. Other member formats are ignored. |
A minimal JSONL or NDJSON file:
{"id":"review-12345","type":"REVIEW","timestamp":1714838400,"text":"Loved it"}
{"id":"review-12346","type":"REVIEW","timestamp":1714838460,"text":"Confusing onboarding"}
A minimal CSV file:
id,type,text,timestamp,plan
review-12345,REVIEW,Loved it,1714838400,Enterprise
review-12346,REVIEW,Confusing onboarding,1714838460,Free
CSV and TSV support quoted fields, including embedded line breaks, UTF-8 BOMs, and CRLF line endings. Keep a consistent field count. Duplicate or empty headers, missing required headers, invalid UTF-8, or broken quoting can fail the file. XLSX, gzip, XML, Parquet, and plain .txt files are not supported.
File-size limits
Limit | Value |
Maximum file size | 2 GiB |
Maximum JSONL line / CSV or TSV row length | 10 MiB per line |
Files over 2 GiB are skipped (we log a warning and advance past them so they don't block newer files). JSONL/NDJSON lines over 10 MiB are recorded as parse failures and processing continues. CSV/TSV logical rows are also limited to 10 MiB; an oversized row fails that file. ZIP processing also applies decompressed-size and compression-ratio safety limits. If you need to ingest more than 2 GiB at once, split it across multiple files.
Atomic uploads — the most important rule
⚠️ Never read your file before it's fully written. Enterpret skips any file whose modification time is less than 10 minutes old. This is intentional: it gives your upload time to finish.
The safe pattern is:
Write your file to a temporary name (e.g.
feedback_2026-05-04.jsonl.tmp).When the write is fully complete, rename it to the final name (
feedback_2026-05-04.jsonl).
Use an atomic rename supported by your SFTP server within the same filesystem after the upload finishes. This reduces the risk of Enterpret reading an incomplete file. Confirm your server’s rename semantics and avoid streaming directly to the final eligible filename.
If your upload tool doesn't support atomic renames, write under one of the in-flight extensions we ignore (`.tmp`, `.partial`, `.swp`, `.lock`, `.crdownload`) and rename to the chosen supported extension only after the write completes.
Files we ignore (hidden / temp / partial)
We skip any file whose name:
Starts with
.(e.g..DS_Store,.staging.jsonl)Starts with
~(e.g.~$open.jsonl)Ends with
.tmp,.partial,.swp,.lock, or.crdownload(case-insensitive)
Use any of these as in-flight extensions if your upload tool doesn't do atomic renames.
File ordering and naming
Files are processed in (modified-time ascending, then path ascending) order. So:
A file uploaded earlier always wins over one uploaded later.
Two files with the same mtime are processed alphabetically by path.
We recommend including a timestamp in your filename (feedback_2026-05-04T14-00.jsonl) for easy troubleshooting, but it's not what we use to order — only the mtime + path is.
Record schema
A record object in JSONL, NDJSON, or JSON uses this schema. CSV/TSV map the required columns to the same fields:
{ "id": "review-12345", "type": "REVIEW", "timestamp": 1714838400, "text": "Loved the new export feature, but onboarding was confusing.", "metadata": [ { "name": "rating", "value": "4" }, { "name": "country", "value": "US" }, { "name": "tags", "value": "feature-request" }, { "name": "tags", "value": "onboarding" } ] }
(For JSONL/NDJSON, use one object per line with no commas or wrapping array. A .json file may instead contain an array of these objects.)
Required fields
Field | Type | Notes |
| string | Unique per record. If you send the same |
| string | Must be exactly |
| number or string | Unix epoch (seconds, ms, μs, or ns — auto-detected by magnitude) or an ISO date in |
| string | The customer feedback. **Must be non-empty after trimming whitespace** — empty-text records are written to the failed-records bucket |
Optional fields
Field | Type | Notes |
| array of | Structured properties — see below. |
Metadata format and gotchas
Metadata is delivered as an array of {name, value} objects, not a flat map. This lets you send the same key multiple times (multi-select tags, multi-line addresses).
"metadata": [ { "name": "rating", "value": "4" }, { "name": "country", "value": "US" }, { "name": "tags", "value": "feature-request" }, { "name": "tags", "value": "onboarding" } ]
Behavior:
A key that appears once is stored as a single string.
A key that appears multiple times is stored as an array, in the order it appears in the file.
Entries with an empty or missing
nameare silently skipped.Send metadata values as strings. Numeric values are also accepted and represented as strings; encode booleans explicitly as
"true"or"false". Objects and arrays are not supported as metadata values.Metadata keys are promoted to top-level filterable fields in the Enterpret dashboard, so make them human-readable (
country, notc1).
ℹ️ Unlike the webhook schema, SFTP metadata does not use "s"/"n"/"b" type indicators. Just send {name, value} pairs.
What happens when something goes wrong
We separate failures into three categories, each with very different behavior. Understanding the difference is the key to diagnosing problems.
1. Connection failures (poll-level)
These prevent us from connecting to your server at all, or from listing the directory. The whole poll fails and no progress is made — we'll retry on the next scheduled poll.
Error you'll see in the integration health dashboard | What it means | What to do |
| We couldn't open a TCP connection. | Check that your server is up, on the right port, and reachable from Enterpret's IP range. Confirm any firewall / VPN allow-list. |
| TCP works, SSH auth failed. | Verify the username, password, or private key. Check |
| The server presented a different SSH host key than the fingerprint we have on file. | Either your server's host key was rotated (legitimate — re-share the new fingerprint with us) or the connection is being intercepted. Don't reuse — investigate. |
| ||
| We connected and authenticated, but can't read the remote directory. |
|
2. File-level failures
These happen when we can read the directory but can't process a specific file. The file is skipped or aborted, and the watermark behavior depends on the failure type.
Failure | What we do | Watermark behavior |
File over 2 GiB | Skip with a warning. | Advances past the file so it doesn't block newer files. |
Unsupported extension (anything other than | Silently skip. | Skipped entirely — use one of the supported extensions. |
Hidden / temp file | Silently skip. | Same as above. |
File mtime is within 10 min stability window | Skip this poll. | Does not advance — we'll reconsider it on the next poll once it's settled. |
3. Record-level failures
These happen when individual records fail validation. For JSONL/NDJSON, malformed lines are recorded and processing continues. For CSV/TSV, a row with the wrong field count can be recorded and skipped, but broken quoting, invalid UTF-8, or oversized rows fail the file. Malformed JSON arrays or ZIP files can also halt file processing. Correct file-level errors before redelivering the export.
Failure | Reason saved on the record |
Missing or empty |
|
Missing/unparseable |
|
Missing |
|
Missing or whitespace-only | missing or empty text |
|
|
Line is malformed JSON (broken syntax, trailing junk after the object) |
|
Line is the literal |
|
Line exceeds the 10 MiB cap |
|
Where to find failed records: Failed records are bundled into a JSON blob and uploaded to an Enterpret-managed S3 bucket under:
sftp/<integration-id>/failed/<DD-MM-YYYY>/<file-name>_<unix-ts>_failed.json
Ask your CSM for a presigned URL or a copy of the blob if you need to debug a specific batch. The blob contains the raw record JSON annotated with _validation_error (or _parse_error + _raw for hard parse failures), so you can see exactly which fields tripped each record.
ℹ️ Failed records are not retried automatically. If you fix the data, re-upload the file (or just the corrected lines) — Enterpret-side deduplication is keyed off id, so re-sending the same id will overwrite the previous version.
Polling, watermarks, and resumability
You don't normally need to think about this — but if a file ever looks "stuck" or duplicate, here's the model:
We track an internal cursor of
(last_modified_epoch, last_processed_path). After each successful file we advance both.Files with mtime older than the cursor's epoch are skipped.
Files with mtime equal to the cursor's epoch are skipped if the path is alphabetically
<=the cursor's path. (Same-mtime files are processed in path order.)Files with mtime newer than the cursor are eligible.
What this means for you:
A file you re-upload gets a new mtime, so we'll reprocess it. Records with the same
idwill overwrite previous versions, not create duplicates.A file you backdate (touch with an older mtime) may be skipped if its mtime is now older than the cursor. Don't manually backdate files unless you also reset the integration with us.
Large files are processed in batches. A fetch emits at most 2,000 records and saves a resume cursor. JSONL/NDJSON and CSV/TSV use byte offsets; JSON and ZIP use record-count resume. Large files can therefore take longer to finish.
Mid-fetch re-uploads are safe but wasteful. If you overwrite a file while we're streaming it, we'll detect that the mtime changed, discard our resume cursor, and start that file over from the beginning on the next poll. Records already ingested are deduplicated downstream, so you won't get duplicates — but you will burn extra polls.
Limits at a glance
Limit | Value |
Max file size | 2 GiB |
Max JSONL line / CSV or TSV row length | 10 MiB |
Records emitted per poll | 2,000 (large files paginate across polls) |
File stability window | 10 minutes (mtime must be at least this old to be picked up) |
Default polling cadence | 4 hours by default; confirm your configured schedule with your CSM |
Supported extension |
|
Supported record types |
|
Troubleshooting checklist
If a file isn't being ingested, run through this list before contacting support:
Is the file in the configured remote directory? Subdirectories are not crawled.
Does the filename use a supported extension? Use
.json,.jsonl,.ndjson,.csv,.tsv, or.zip. Case does not matter.Does the filename start with
.or~, or end in.tmp,.partial,.swp,.lock,.crdownload? Those are ignored on purpose.Is the file's modification time at least 10 minutes ago?
statit on the server. If you just uploaded it, wait a poll cycle.Does the content match its format? JSONL/NDJSON use one object per line; JSON may use an array; CSV/TSV require the correct header and consistently quoted rows. ZIP members must use supported formats.
Keep each JSONL line or CSV/TSV logical row within 10 MiB. Split large exports across files below 2 GiB.
If records are failing validation, ask for the failed-records blob to see the exact reason per record.
Frequently asked questions
How quickly will my data appear in Enterpret?
The current default polling interval is four hours, and files normally must be at least 10 minutes old before they are eligible. Your connection can use a different configured schedule. Large files are fetched in batches, and processing adds time; the polling interval does not guarantee when feedback appears.
Can I send updates / corrections?
Yes. Re-upload a record with the same id and the new content; the previous version is overwritten downstream. Use a new file (or the same file with a new mtime) so we re-read it.
Can I delete records via SFTP?
Not via the SFTP path. Contact your CSM for record deletion / GDPR requests.
Will Enterpret delete or move my files after processing?
No. Files stay where you put them. You're responsible for cleanup. We recommend a daily/weekly rotation: move processed files to a sibling archive/ directory (which we don't read) once you're confident they've been ingested.
Can I have multiple SFTP integrations?
Yes. Each integration has its own credentials, remote directory, and source-type label, and is polled independently.
What's the difference between SFTP and the Webhook integration?
Webhook: real-time push, you call our API. Best for live data and small batches.
SFTP: scheduled pull, we read your files. Best for batch exports, vendor feeds, and anything that already produces files.
SFTP accepts the REVIEW schema in this guide. Do not send the complete Webhook request wrapper or assume the Webhook metadata format applies.
Which file formats can I use?
Use JSON, JSONL/NDJSON, CSV, TSV, or ZIP files that follow the layouts and limits above. JSONL/NDJSON and CSV/TSV can continue from saved byte boundaries across polls; JSON and ZIP use record-count resume. Choose a supported format your export tool can produce, and finish uploading the file before Enterpret processes it.
Can I send CONVERSATION, SURVEY, AUDIO_RECORDING, or FORUM_CONVERSATION_THREAD records via SFTP?
Not today. Those record types require structured fields (multi-message conversations, Q&A pairs, audio URLs) that the flat SFTP record shape doesn't carry. Use the Webhook integration for those.
My SFTP server's host key changed — what do I do?
Until self-serve key rotation is available, delete and recreate the integration to pick up a new host key. The fingerprint is captured automatically on first successful connect (TOFU).
Note: Recreating resets the watermark, so existing files may be reprocessed (no duplicates downstream due to ID dedupe, but it may consume extra poll cycles).
If preserving watermark state is critical, contact your CSM—engineering can update the stored fingerprint manually.
Can I use a non-standard port?
Yes — share the port number when you set up the integration.
If you run into anything not covered here, message your CSM with: the integration name, the filename in question, the time you uploaded it, and (if available) the failure message from the integration dashboard. These details help Support investigate the affected file.